Binary Tree Right Side View

Problem statement
You are given the root of a binary tree. Imagine standing to the right of the tree and looking at it from that side — return the values of the nodes you can see, from top to bottom.
At each depth, exactly one node is visible from the right: the one with nothing further right blocking it at that level. This is not the same as "the rightmost value in the tree's array form" — it depends on the tree's actual shape, since a node can be visible even if it's a left child, as long as no node further right exists at its depth.
Examples
Example 1
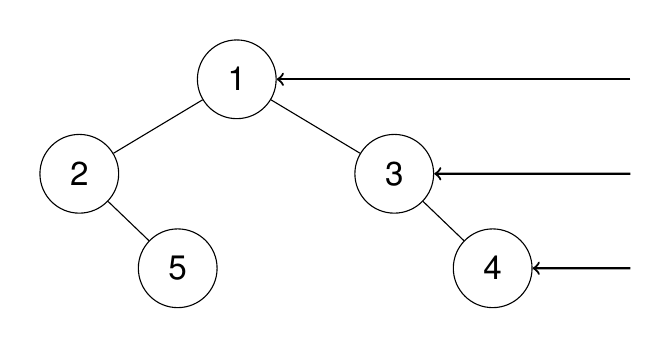
Input: root = [1,2,3,null,5,null,4]
Output: [1,3,4]
Explanation: At depth 0, only 1 exists. At depth 1, both 2 and 3 exist, and 3 is further right, so it's the one visible. At depth 2, the only node is 4 (the right child of 3) — 5 (the right child of 2) is at the same depth but blocked from view by 4 being further right.
Example 2
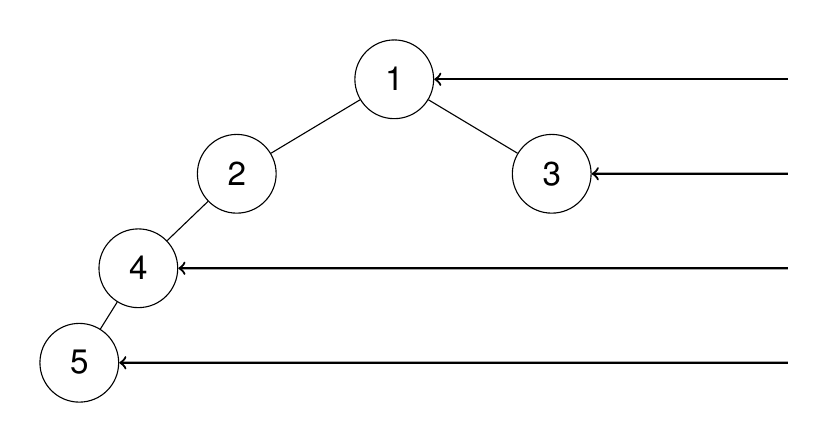
Input: root = [1,2,3,4,null,null,null,5]
Output: [1,3,4,5]
Explanation: Depth 0 is just 1. Depth 1 has 2 and 3; 3 is rightmost. Depth 2 has only 4 (a left child of 2), so it's the one visible even though it isn't on the tree's right edge. Depth 3 has only 5, a left child of 4.
Hints
Approach
Optimal: DFS, right child first
Intuition
If a depth-first search always visits a node's right child before its left child, then the very first time it reaches any given depth, it must be doing so through the rightmost path available — any node further right at that depth would have been reached first. So a single DFS pass, right-first, that records a node's value only the first time its depth is newly reached, produces exactly the right side view. This avoids ever holding a full level's worth of nodes in memory at once, which is the real advantage over BFS on a wide tree.
Steps
- Keep a result list, plus a recursive
dfs(node, depth)function. - If
nodeis empty, return — there's nothing to do. - If
depthequals the current length of the result list, this is the first time this depth has been reached, so appendnode's value. - Recurse into the right child first, with
depth + 1. - Then recurse into the left child, also with
depth + 1. - Call
dfs(root, 0)once; the result list is the answer.
Dry run
root = [1, 2, 3, 4, null, null, null, 5] (1's children are 2, 3; 2's only child is 4 on the left; 4's only child is 5 on the left)
| call (depth) | is depth == len(res)? | recorded | then recurses into |
|---|---|---|---|
| dfs(1, 0) | yes (0 == 0) | 1 | right (3), then left (2) |
| dfs(3, 1) | yes (1 == 1) | 3 | right (null), left (null) |
| dfs(2, 1) | no (1 != 2) | — | right (null), left (4) |
| dfs(4, 2) | yes (2 == 2) | 4 | right (null), left (5) |
| dfs(5, 3) | yes (3 == 3) | 5 | right (null), left (null) |
Result, in the order values were recorded: [1, 3, 4, 5], matching the expected output. Node 3 is recorded before node 2 is even visited, because right-first order reaches depth 1's rightmost node first.
Edge cases: an empty tree makes the very first call return immediately, leaving the result list empty. A tree that is a single straight line (all left children, say) still works, because at each depth there is only one node, so it is trivially the first — and only — one reached at that depth.
Complexity
Time O(n) - Every node is visited exactly once by the recursion, with O(1) work at each node beyond the two recursive calls.
Space O(h) - Only the recursion's call stack is used, one frame per node on the current root-to-leaf path, so O(log n) for a balanced tree and up to O(n) for a skewed one — this depends on the tree's height, not its width, which is the key difference from the BFS approach.
class Solution:
    def rightSideView(self, root: "TreeNode | None") -> list[int]:
        res: list[int] = []

        def dfs(node: "TreeNode | None", depth: int) -> None:
            if node is None:
                return
            if depth == len(res):
                res.append(node.val)
            dfs(node.right, depth + 1)
            dfs(node.left, depth + 1)

        dfs(root, 0)
        return res


class TreeNode:
    def __init__(self, val=0, left=None, right=None):
        self.val = val
        self.left = left
        self.right = right


def build_tree(values):
    from collections import deque

    if not values or values[0] is None:
        return None
    root = TreeNode(values[0])
    queue = deque([root])
    i = 1
    n = len(values)
    while queue and i < n:
        node = queue.popleft()
        if i < n:
            v = values[i]
            i += 1
            if v is not None:
                node.left = TreeNode(v)
                queue.append(node.left)
        if i < n:
            v = values[i]
            i += 1
            if v is not None:
                node.right = TreeNode(v)
                queue.append(node.right)
    return root


def fmt(values: list[int]) -> str:
    return "[" + ",".join(str(x) for x in values) + "]"


if __name__ == "__main__":
    sol = Solution()
    print(fmt(sol.rightSideView(build_tree([1, 2, 3, None, 5, None, 4]))))  # [1,3,4]
print(fmt(sol.rightSideView(build_tree([1, 2, 3, 4, None, None, None, 5])))) # [1,3,4,5]RecapThe whole problem in a few lines, for the night before
- Spot it: "what's visible looking at a binary tree from the right, top to bottom" — one node per depth, the one furthest right with nothing blocking it
- Idea: BFS and take the last node processed per level, or DFS with right child visited before left and keep only the first node reached at each new depth
- Cost: O(n) time either way; O(w) space for BFS (bounded by the widest level), O(h) space for DFS (bounded by height)
- Trap: visiting left before right in the DFS version silently produces the left side view instead — the "first reached at each depth" trick only works because right is explored first
Interview follow-ups
Return the left side view instead.
Flip the "first at each depth" and "last in each level" rules to their opposite side. In the DFS version, recurse into the left child before the right child, so the first node reached at each new depth is now the leftmost one. In the BFS version, record the first node dequeued in each level instead of the last one. Both changes are a one-line swap; the time and space complexity stay exactly the same.
The tree can be a million nodes wide but only twenty levels deep. Which approach do you use, and why?
The DFS (right-first) approach, because its memory use is bounded by height, not width. BFS's queue would need to hold on the order of half a million nodes at the widest level, while DFS's recursion never holds more than about twenty stack frames at once — the same O(n) time either way, but a dramatically smaller memory footprint when width vastly exceeds height.
Frequently asked questions
Because "first to arrive" and "furthest right" line up exactly when the search always tries right before left. Any node that lies further right at the same depth would necessarily be explored before a node further left, so the first node the recursion ever reaches at a given depth is guaranteed to be the rightmost one at that depth — no comparison between siblings is ever needed.
No — a node's position in an array-with-nulls representation reflects where its parent placed it, not whether anything actually blocks it from view. A left child can be the visible node at its depth if no node exists further right at that same depth, which the BFS and DFS approaches both handle correctly by tracking real nodes and depths, not array positions.
BFS's queue holds an entire level of the tree at once, and the widest level of a tree can be close to n/2 nodes (for example, the bottom row of a complete binary tree). DFS's recursion stack only ever holds nodes along the current root-to-leaf path, which is bounded by the tree's height — so on a wide, shallow tree, DFS's O(h) beats BFS's O(w) by a wide margin, even though both are O(n) in time.
The same shape appears when rendering a layered configuration or override system: given a hierarchy of settings inherited from parent to child, "what value is actually in effect at each level" is exactly a rightmost-visible-node question if later overrides are modeled as being further to one side. It also matches summarizing the deepest active branch at each depth of a call graph or dependency tree.
No — the algorithms track nodes and depths, and only read a node's value once they've already decided that node is the one visible at its depth. Duplicate values elsewhere in the tree never affect which node is selected.