Find if Path Exists in Graph
Problem statement
You have n nodes numbered 0 to n - 1 and a list of edges. Each edge [u, v] is a two-way link between nodes u and v. Return true if you can travel from source to destination by following edges, and false if you can't.
There are no duplicate edges and no edge from a node to itself. Some nodes may have no edges at all.
Think of the nodes as hosts and the edges as network links: the question is "can host source reach host destination?"
Examples
Example 1
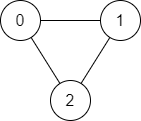
Input: n = 3, edges = [[0,1],[1,2],[2,0]], source = 0, destination = 2
Output: true
Explanation: Node 0 is linked straight to node 2, and also reaches it through node 1. Either route is enough.
Example 2
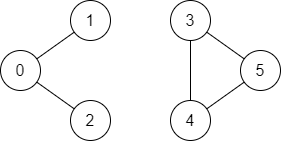
Input: n = 6, edges = [[0,1],[0,2],[3,5],[5,4],[4,3]], source = 0, destination = 5
Output: false
Explanation: Nodes 0, 1 and 2 form one group and nodes 3, 4 and 5 form another. No edge joins the two groups, so 0 can't reach 5.
Hints
source and mark it reached. Which other nodes can you mark from there, and when can you stop?Approach
Optimal: Union-find
Intuition
Forget walking. Put every node in its own group at the start. Each edge says "these two nodes are connected", so merge their two groups into one. After all edges are processed, two nodes can reach each other exactly when they are in the same group.
A union-find (also called a disjoint-set) keeps these groups. Each group has one representative node, its root. Every node points to a parent, and following parents leads to the root. find(x) returns x's root; union(a, b) makes one root point to the other. Two small tricks keep the chains short: attach the smaller group under the bigger one, and while finding, point nodes closer to the root.
Steps
- Set
parent[i] = iandsize[i] = 1for every node. find(x): whileparent[x] != x, setparent[x] = parent[parent[x]](skip a level) and movexup. Returnx.- For each edge
[u, v]: find both roots. If they differ, attach the smaller group's root under the larger one and add the sizes. - Return
find(source) == find(destination).
Dry run
n = 6, edges = [[0,1],[0,2],[3,5],[5,4],[4,3]], source = 0, destination = 5
| edge | roots | action | groups |
|---|---|---|---|
| [0,1] | 0, 1 | merge | {0,1} {2} {3} {4} {5} |
| [0,2] | 0, 2 | merge | {0,1,2} {3} {4} {5} |
| [3,5] | 3, 5 | merge | {0,1,2} {3,5} {4} |
| [5,4] | 3, 4 | merge | {0,1,2} {3,4,5} |
| [4,3] | 3, 3 | same group, skip | {0,1,2} {3,4,5} |
find(0) is 0 and find(5) is 3 → different → false.
Complexity
Time O((n + E)·α(n)) - Setting up the parent list is O(n). Each edge does one union, and each union does two finds. With path halving and union by size, a find costs α(n) on average — the inverse Ackermann function, which is at most 4 for any real input size. So in practice this is linear, like BFS.
Space O(n) - We store one parent and one size per node. No adjacency list is built, so it uses less memory than BFS when there are many edges. The input edge list is not counted.
from typing import List


class Solution:
    def validPath(self, n: int, edges: List[List[int]], source: int, destination: int) -> bool:
        parent = list(range(n))
        size = [1] * n

        def find(x: int) -> int:
            while parent[x] != x:
                parent[x] = parent[parent[x]]
                x = parent[x]
            return x

        for u, v in edges:
            ru, rv = find(u), find(v)
            if ru == rv:
                continue
            if size[ru] < size[rv]:
                ru, rv = rv, ru
            parent[rv] = ru
            size[ru] += size[rv]

        return find(source) == find(destination)


if __name__ == "__main__":
    print(str(Solution().validPath(3, [[0, 1], [1, 2], [2, 0]], 0, 2)).lower())  # true
print(str(Solution().validPath(6, [[0, 1], [0, 2], [3, 5], [5, 4], [4, 3]], 0, 5)).lower()) # falseRecapThe whole problem in a few lines, for the night before
- Spot it: "can node A reach node B?" in an undirected graph given as an edge list
- Idea: build an adjacency list, then BFS from
sourceand stop when you reachdestination; or union-find the edges and compare roots - Cost: O(n + E) time, O(n + E) space (union-find: O(n) space)
- Trap: forgetting to add each edge in both directions, or not marking nodes visited — the search then loops forever on a cycle
Interview follow-ups
Return the actual path, not just true or false.
During BFS, store
parent[next] = nodeeach time you queue a new node. When you reachdestination, walk back throughparenttosourceand reverse the list. Because BFS explores in rings, this path uses the fewest edges possible. Time and space stay O(n + E).The edges are one-way (a directed graph). What changes?
Add each edge only once:
graph[u].append(v), not the reverse. BFS then follows edges only in their direction, and the rest of the code is unchanged. Union-find no longer works, because it treats every link as two-way.Many queries arrive: "are a and b connected?", with new links added between queries.
Use union-find. Each new link is one
union, and each query is twofindcalls, both near O(1). Re-running BFS for every query would cost O(n + E) each time. If links can also be removed, union-find can't undo merges easily, and you'd need a different structure or a periodic rebuild.
Frequently asked questions
The edge list only tells you "these pairs are linked". To find one node's neighbours from it, you'd have to scan every edge — that's exactly what makes the brute force slow. An adjacency list groups the neighbours by node, so each lookup is instant. Building it costs one pass over the edges, which pays for itself immediately.
Yes. Swap the queue for a stack (or use recursion) and everything else stays the same, with the same O(n + E) cost. With up to 200,000 nodes, a recursive DFS can overflow the call stack on a long chain, especially in Python. An iterative DFS with your own stack, or BFS, avoids that.
When edges keep arriving and you need to answer "are these two connected?" many times. Union-find absorbs each new edge in near-constant time and answers each question just as fast, without re-walking the graph. For one single question on a fixed graph, BFS and union-find are equally good. BFS can also return the actual path if you record parents; union-find can't.
If you mark on removal, a node can be added several times by different neighbours before it's processed. The answer is still correct, but the queue can grow much larger and the same node is explored more than once. Marking on add guarantees each node enters the queue at most once.
Reachability is at the heart of network and dependency questions. Can this pod reach the database through the allowed security-group rules? Is this service still connected to the rest after a link goes down? Which hosts are in the same network partition? Each is this problem with real node names.