K Closest Points to Origin

Problem statement
You're given a list of points on a 2D plane, points, where each point is
[x, y], and an integer k. Return the k points that are closest to the
origin (0, 0), in any order — think of it as picking the k nearest
healthy replicas to a client's location, or the k closest data-center
regions to where a request came from.
Distance is ordinary straight-line (Euclidean) distance. The answer set is guaranteed to be unique, even though the order you return it in doesn't matter.
Examples
Example 1
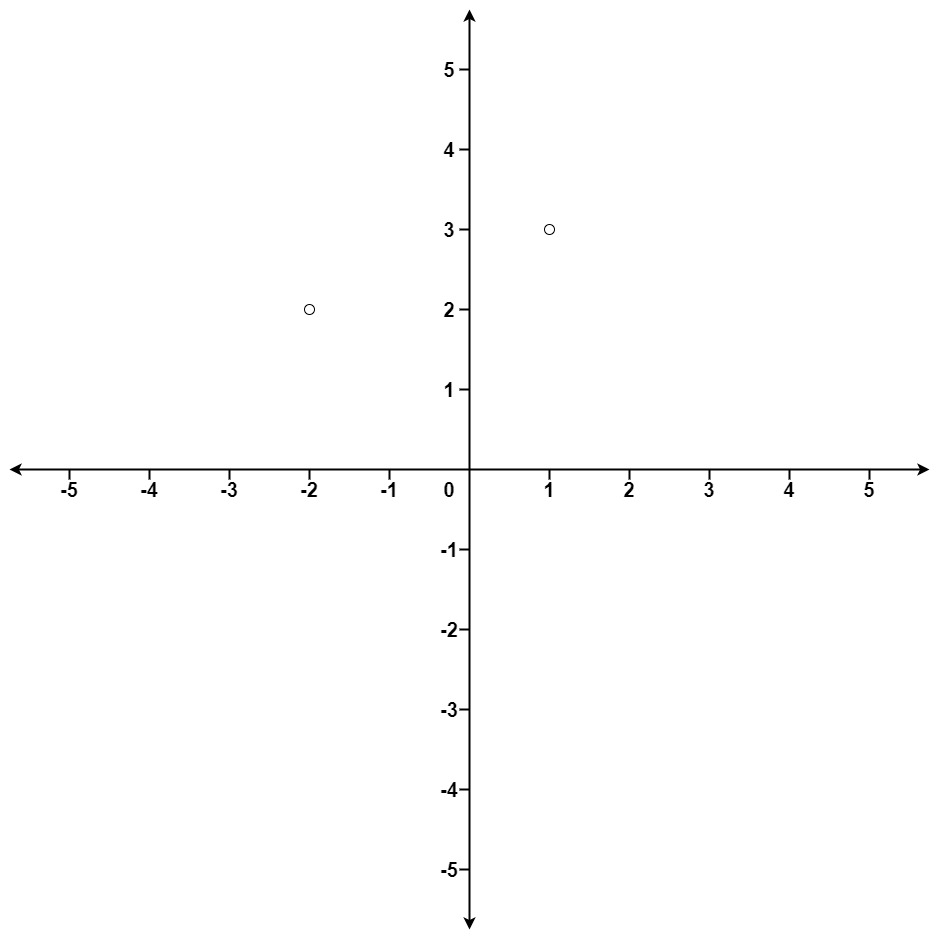
Input: points = [[1,3],[-2,2]], k = 1
Output: [[-2,2]]
Explanation: (1, 3) is √10 from the origin; (-2, 2) is √8. Since √8 < √10, (-2, 2) is the closer point, so it's the one closest point returned.
Example 2
Input: points = [[3,3],[5,-1],[-2,4]], k = 2
Output: [[3,3],[-2,4]]
Explanation: The squared distances are 18, 26 and 20 for (3,3), (5,-1) and (-2,4). The two smallest belong to (3,3) and (-2,4), so those are the two closest points — (5,-1), the farthest, is left out.
Hints
x² + y² directly gives the exact same ordering and skips the floating-point math entirely.Approach
Optimal: Quickselect by distance
Intuition
This is really the same "find the k smallest values" question as Kth Largest Element in an Array, just with the comparison key being a computed squared distance instead of the value itself, and looking for the smallest k instead of a single boundary value. Partition points around a pivot's distance so closer points land before it and farther points land after it. If the pivot ends up exactly at index k, everything before it — the first k points — is the answer. Otherwise, only continue into the side that could still contain that boundary.
Steps
- Pick a pivot point (randomly, to avoid a bad split on adversarial input) and partition the current range so points with squared distance ≤ the pivot's come first, and farther points come after — this places the pivot at its correct sorted-by-distance position.
- If the pivot's final index equals
k, every point before it is the answer — stop. - If the pivot's final index is less than
k, the boundary is still to the right — continue into the right side only. - If it's greater than
k, continue into the left side only. - Once the boundary is settled, return the first
kpoints.
Dry run
points = [[3,3],[5,-1],[-2,4]], k = 2 (distances 18, 26, 20; swaps
inside each partition are omitted here — the key thing to track is which
side keeps being explored):
| round | range | pivot (dist) | pivot's final index | vs k (2) | next |
|---|---|---|---|---|---|
| 1 | [0,2] | (-2,4), 20 | 1 | 1 < 2 → boundary is to the right | recurse [2,2] |
| 2 | [2,2] | single point | 2 | matches k | done |
The first two points at that point are (3,3) and (-2,4) — matching
Example 2.
Edge cases: k equal to the number of points means the loop can stop
before partitioning at all, since every point is included. Two points at
identical distance may land on either side of a pivot, but since the
answer set is guaranteed unique, this never produces a wrong result.
Complexity
Time Average - O(n); worst case O(n²), made very unlikely by a random pivot.
Space O(1) - extra, partitioning in place.
import random
from typing import List


class Solution:
    def kClosest(self, points: List[List[int]], k: int) -> List[List[int]]:
        points = points[:]  # avoid mutating the caller's list

        def dist(p: List[int]) -> int:
            return p[0] * p[0] + p[1] * p[1]

        def partition(left: int, right: int) -> int:
            pivot_pos = random.randint(left, right)
            points[pivot_pos], points[right] = points[right], points[pivot_pos]
            pivot_dist = dist(points[right])

            store = left
            for i in range(left, right):
                if dist(points[i]) <= pivot_dist:
                    points[i], points[store] = points[store], points[i]
                    store += 1
            points[store], points[right] = points[right], points[store]
            return store

        left, right = 0, len(points) - 1
        while left < right:
            pivot_index = partition(left, right)
            if pivot_index == k:
                break
            elif pivot_index < k:
                left = pivot_index + 1
            else:
                right = pivot_index - 1

        return points[:k]


if __name__ == "__main__":
    print(Solution().kClosest([[1, 3], [-2, 2]], 1))          # [[-2, 2]]
print(Solution().kClosest([[3, 3], [5, -1], [-2, 4]], 2)) # order may vary, e.g. [[3, 3], [-2, 4]]RecapThe whole problem in a few lines, for the night before
- Spot it: "return the k closest / smallest-by-some-metric items from a list" — same shape as Kth Largest Element, just with a computed key
- Idea: compare squared distance to skip the square root; a size-k max-heap keeps the k closest by discarding the current farthest; quickselect partitions by distance and only recurses toward index k
- Cost: sort O(n log n); heap O(n log k); quickselect average O(n), worst O(n²)
- Trap: computing the real Euclidean distance with a square root is unnecessary and slower — squared distance always gives the identical ordering
Interview follow-ups
What if points arrived as a continuous stream, and you needed the k closest seen so far updated after every new point?
The max-heap-of-size-k approach adapts directly to a stream: push each new point and pop the farthest one if the heap grows past size k. Quickselect doesn't suit a stream nearly as well, since a single call needs the whole current dataset available to partition against.
What if distance should be measured in 3D, or with a different metric entirely, like Manhattan distance?
Only the distance calculation changes —
x² + y² + z²for 3D, or|x| + |y|for Manhattan distance — every other part of all three approaches (the sort key, the heap's ordering, quickselect's partition condition) stays exactly the same, since none of them actually cared what the distance formula was, only that its results can be compared.
Frequently asked questions
Square root is order-preserving for non-negative numbers, so comparing x² + y² gives exactly the same ordering as comparing √(x² + y²). Skipping the square root avoids floating-point rounding entirely and is simply less work per comparison.
Because the goal this time is to keep the k smallest distances, so the point that should be discarded when the heap overflows is the one with the largest distance. A max-heap puts that point on top, ready to pop — the mirror image of how Kth Largest Element's min-heap keeps the smallest value on top to discard, because that problem wanted to keep the k largest values instead.
The problem only asks for the set of k closest points, not a particular ordering among them, and it guarantees that set is unique. All three approaches here can hand the points back in whatever order they happen to land in — sorted order, heap-pop order, or partition order — and still be correct.
Finding the k nearest resources to a location — the closest healthy replicas to a client, the nearest data-center regions to a request's origin — is exactly a nearest-neighbours query, and comparing squared distances instead of true distances is the same trick used in real geo-routing code to avoid unnecessary floating-point work.