Same Tree

Problem statement
You are given the roots of two binary trees, p and q. Return true if the two trees are the same — meaning they have exactly the same shape (the same nodes present in the same left/right positions) and every corresponding pair of nodes holds the same value. Return false otherwise.
This is the same question you'd ask when comparing two versions of a config tree, two parsed ASTs, or two directory structures for drift: not just "do they contain the same values somewhere", but "is every node in exactly the same place with exactly the same value."
Examples
Example 1
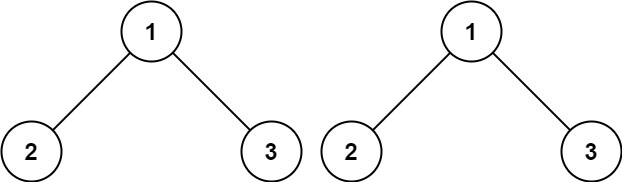
Input: p = [1,2,3], q = [1,2,3]
Output: true
Explanation: both trees have root 1 with left child 2 and right child 3 — identical shape and identical values at every position.
Example 2
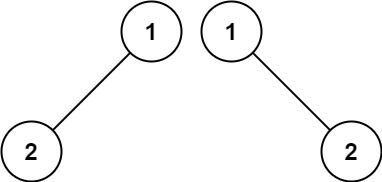
Input: p = [1,2], q = [1,null,2]
Output: false
Explanation: in p, the 2 is a left child; in q, the 2 is a right child. Same values overall, but different shapes, so the trees are not the same.
Example 3
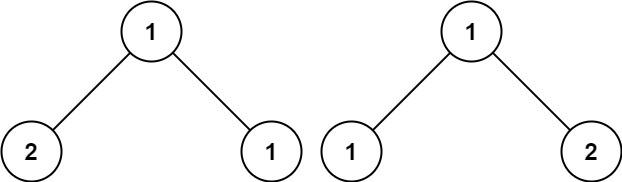
Input: p = [1,2,1], q = [1,1,2]
Output: false
Explanation: both trees have the same shape (a root with two children), but the left and right values are swapped — p's left child is 2 and right child is 1, while q's are the other way around.
Hints
Approach
Optimal: Iterative BFS
Intuition
Instead of recursing down and combining results on the way back, walk both trees in lockstep using a queue of pairs: at every step, take one pair (node from p, node from q) off the queue and compare them directly. If they match, queue up their two children as new pairs — (p.left, q.left) and (p.right, q.right) — and keep going. The moment any pair fails to match (different values, or one side missing where the other isn't), the whole check can return false right away, without processing whatever else is still sitting in the queue.
Steps
- Put the pair
(p, q)— the two roots — into a queue. - While the queue isn't empty, remove the next pair.
- If both nodes in the pair are
null, this pair matches — move on to the next pair in the queue. - If exactly one of the two is
null, the trees differ in shape here — returnfalseimmediately. - If both exist but their values differ, return
falseimmediately. - Otherwise, queue up the pair of left children and the pair of right children, and continue.
- If the queue empties without ever returning
false, every pair matched — returntrue.
Dry run
p = [1,2], q = [1,null,2] (Example 2): p has root 1 with a left child 2 and no right child; q has root 1 with no left child and a right child 2.
| step | pair dequeued | check | action |
|---|---|---|---|
| 1 | (1, 1) |
both non-null, values equal | queue (2, null) and (null, 2) |
| 2 | (2, null) |
one is null, the other isn't | return false |
Result: false, matching Example 2 — the mismatch is caught as soon as the left-child pair is dequeued, without ever looking at the right-child pair still waiting in the queue.
Edge cases: if both roots are null, the very first pair dequeued is (null, null), which is treated as a match, and the queue is then empty — the loop ends and returns true.
Complexity
Time O(n) - where n is the number of nodes in the smaller tree. Each pair of corresponding nodes is enqueued and dequeued exactly once, and the work per pair (comparing values and queueing the next pair of children) is O(1).
Space O(w) - where w is the maximum width of either tree at any level. The queue holds pairs of nodes level by level, so its size tracks how wide the trees get, not how deep — the opposite trade-off from the recursive version's stack.
from collections import deque
from typing import Optional


# Definition for a binary tree node.
class TreeNode:
    def __init__(self, val=0, left=None, right=None):
        self.val = val
        self.left = left
        self.right = right


class Solution:
    def isSameTree(self, p: Optional[TreeNode], q: Optional[TreeNode]) -> bool:
        queue = deque([(p, q)])
        while queue:
            node1, node2 = queue.popleft()
            if node1 is None and node2 is None:
                continue
            if node1 is None or node2 is None:
                return False
            if node1.val != node2.val:
                return False
            queue.append((node1.left, node2.left))
            queue.append((node1.right, node2.right))
        return True


def build_tree(values: list) -> Optional[TreeNode]:
    if not values or values[0] is None:
        return None
    root = TreeNode(values[0])
    queue = deque([root])
    i = 1
    while queue and i < len(values):
        node = queue.popleft()
        if i < len(values):
            if values[i] is not None:
                node.left = TreeNode(values[i])
                queue.append(node.left)
            i += 1
        if i < len(values):
            if values[i] is not None:
                node.right = TreeNode(values[i])
                queue.append(node.right)
            i += 1
    return root


if __name__ == "__main__":
    def fmt(b: bool) -> str:
        return "true" if b else "false"

    p1, q1 = build_tree([1, 2, 3]), build_tree([1, 2, 3])
    p2, q2 = build_tree([1, 2]), build_tree([1, None, 2])
    p3, q3 = build_tree([1, 2, 1]), build_tree([1, 1, 2])

    print(fmt(Solution().isSameTree(p1, q1)))
    print(fmt(Solution().isSameTree(p2, q2)))
print(fmt(Solution().isSameTree(p3, q3)))RecapThe whole problem in a few lines, for the night before
- Spot it: "check if two trees are the same" — compares both shape and values at every corresponding position, not just contents
- Idea: recursively check (both null) or (both non-null, same value, same left subtree, same right subtree); fail fast on the first mismatch
- Cost: O(n) time either way; O(h) space for recursive DFS (call stack), O(w) space for iterative BFS (widest level)
- Trap: treating "same values present" as equivalent to "same tree" — position and shape matter just as much as the values themselves
- Remember:
isSameTreeis the building block for Subtree of Another Tree and (with left/right swapped on one side) Symmetric Tree
Interview follow-ups
Instead of true/false, return the first path (list of values) where the two trees diverge.
Thread a running path (say, a list of values from the root down to the current node) through the recursion, and the moment a mismatch is found — differing values, or one side
nulland the other not — return that accumulated path instead of justfalse. Every other case still recurses and appends the current node's value before descending. This keeps the same O(n) time bound in the worst case, with O(h) extra space for the path itself, and turns a bare yes/no answer into something a human can act on immediately.The trees are enormous and stored on different machines — comparing every node would be far too much network traffic.
Instead of walking both trees, compute a content-based hash of each subtree (e.g., combine a node's own value with the hashes of its left and right subtrees) and compare only the two root hashes first. If the root hashes differ, the trees definitely differ, and you can then recursively descend and compare hashes level by level to find where they diverge, only pulling the actual node data across the network for the specific branch that doesn't match. This turns "compare everything" into "fetch just enough to localize the difference."
What if node values can repeat, and structural equality (ignoring values entirely) is all that matters?
Drop the value comparison from the equality check entirely: two nodes now "match" as long as they agree on which of their two children exist (both present, both absent, or the same one present on both sides), and the recursion into left and right subtrees proceeds exactly as before. The time and space complexity are unchanged, since the value check was already O(1) — removing it just changes what counts as a match, not how much work is done.
Frequently asked questions
Checking the current pair's null-ness and values first means a mismatch is caught at the shallowest possible point, before any deeper (and pointless) recursive calls are made. If the roots already have different values, there is no reason to ever compare their subtrees — the answer is already false. This short-circuiting is what keeps the approach at O(n) instead of doing extra unnecessary work.
No — that would be a much weaker check. p = [1,2,3] and a tree shaped like [1,3,2] contain the same three values, but they are not the "same tree" under this problem's definition, since the values sit in swapped positions. This problem cares about structure and position together, not just which values appear somewhere in the tree.
Subtree of Another Tree reuses isSameTree directly: it walks one tree looking for any node where isSameTree(that node, the other tree's root) returns true. Symmetric Tree is a variant of this same comparison, but instead of comparing a tree to a second, separate tree, it compares a tree's left subtree to its own right subtree, with left and right swapped at every step (checking p.left against q.right and p.right against q.left) to test for mirror symmetry.
Yes — GeeksforGeeks describes an O(1)-extra-space approach using Morris traversal, which temporarily rewires null right-pointers into "threads" back to an ancestor to simulate the call stack without actually using one, then removes the threads afterward. It reaches the same O(n) time bound with O(1) auxiliary space instead of O(h) or O(w), but the bookkeeping is intricate enough that it's rarely worth reaching for outside of a strict memory-constrained setting.
Comparing two tree-shaped structures for exact equality is a common building block: diffing two versions of a parsed config, verifying that a deployed resource tree matches its declared spec, or checking that two ASTs produced by different runs of a parser agree. The core lesson here — define equality recursively in terms of the roots and their subtrees, and fail fast on the first mismatch — applies directly to any of those comparisons.