Search a 2D Matrix

Problem statement
You get a grid of integers, matrix, with m rows and n columns, and it is sorted in a particular way: read left to right along a row, the values only go up, and the first value of each row is bigger than the last value of the row above it. Read that way, the whole grid is really one long sorted sequence that just happens to be wrapped onto several rows.
Given a target value, decide whether it appears anywhere in the grid — return true if it does and false if it doesn't. Because the grid is fully sorted end to end, you should be able to answer in O(log(m * n)) time: about the same number of steps a binary search would take on one flat array of m * n values, not a search that grows with both dimensions separately.
Examples
Example 1
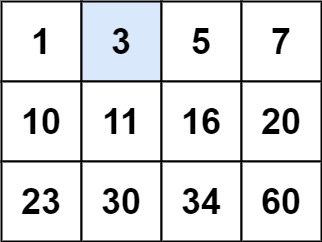
Input: matrix = [[1,3,5,7],[10,11,16,20],[23,30,34,60]], target = 3
Output: true
Explanation: Reading the grid row by row, [1, 3, 5, 7, 10, 11, 16, 20, 23, 30, 34, 60] is one sorted sequence, and 3 is in it (row 0, column 1).
Example 2
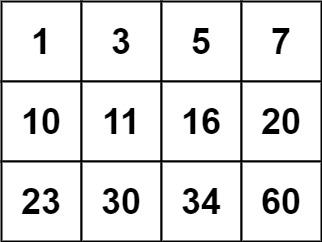
Input: matrix = [[1,3,5,7],[10,11,16,20],[23,30,34,60]], target = 13
Output: false
Explanation: 13 would have to sit between 11 and 16 in that same sorted sequence, but no cell holds it, so the answer is false.
Hints
Approach
Optimal: Flattened binary search
Intuition
Because the last value of every row is smaller than the first value of the next row, reading the matrix row by row gives one single sorted sequence of m * n values — there's no need to treat it as m separate sorted rows at all. That means a single binary search, run directly over that imagined 1D sequence, is enough. This is what makes it faster than the row-by-row version: one O(log(m*n)) search instead of m separate O(log n) searches.
The only trick is translating a position in that imagined 1D array back into a (row, column) pair, which integer division and remainder do for free: position p in a grid with n columns sits at row = p // n, column = p % n.
Steps
- Let
rowsandcolsbe the matrix's dimensions, and treat the matrix as one sorted array of lengthrows * cols. - Set
left = 0andright = rows * cols - 1. - While
left <= right, computemid = left + (right - left) / 2and look upvalue = matrix[mid / cols][mid % cols].- If
value == target, returntrue. - If
value < target, moveleft = mid + 1. - Otherwise move
right = mid - 1.
- If
- If the loop ends without a match, return
false.
Dry run
matrix = [[1,3,5,7],[10,11,16,20],[23,30,34,60]] (cols = 4), target = 13
| left | right | mid | row, col | value | action |
|---|---|---|---|---|---|
| 0 | 11 | 5 | (1, 1) | 11 | 11 < 13 → left = 6 |
| 6 | 11 | 8 | (2, 0) | 23 | 23 > 13 → right = 7 |
| 6 | 7 | 6 | (1, 2) | 16 | 16 > 13 → right = 5 |
| 6 | 5 | — | loop ends (left > right) | — | return false |
No index ever lands on 13, which matches example 2's expected output.
Edge cases: a 1-row or 1-column matrix collapses into a plain binary search over that single row or column, and the index math still works unchanged.
Complexity
Time O(log(m·n)) - one binary search runs over the full m*n cells treated as a single sorted sequence, so the number of steps grows with the log of the total cell count rather than with m and n separately. This is the bound the problem statement asks for.
Space O(1) - only two pointers and a midpoint are kept, no matter how large the matrix is.
class Solution:
    def searchMatrix(self, matrix: list[list[int]], target: int) -> bool:
        rows, cols = len(matrix), len(matrix[0])
        left, right = 0, rows * cols - 1
        while left <= right:
            mid = left + (right - left) // 2
            value = matrix[mid // cols][mid % cols]
            if value == target:
                return True
            if value < target:
                left = mid + 1
            else:
                right = mid - 1
        return False


if __name__ == "__main__":
    matrix = [[1, 3, 5, 7], [10, 11, 16, 20], [23, 30, 34, 60]]
    print(str(Solution().searchMatrix(matrix, 3)).lower())   # true
print(str(Solution().searchMatrix(matrix, 13)).lower()) # falseRecapThe whole problem in a few lines, for the night before
- Spot it: a grid where rows are sorted and each row starts after the previous row ends, with an O(log(m*n)) time limit
- Idea: treat the whole grid as one flattened sorted array; binary search it directly using row = mid / cols, col = mid % cols
- Cost: O(log(m·n)) time, O(1) space (binary search per row: O(m·log n); full scan: O(m·n))
- Trap: binary searching every row separately still passes the examples but is O(m·log n), not the O(log(m·n)) the problem actually asks for
Interview follow-ups
What if columns are also sorted top to bottom, but rows are no longer guaranteed to start after the previous row ends (LeetCode 240, Search a 2D Matrix II)?
The flattening trick stops working, because the grid is no longer one sorted sequence — only each row and each column is sorted on its own. The usual fix is to start at the top-right corner and move: step left when the current value is too big, step down when it's too small. That visits at most rows + cols cells, giving O(m + n) time instead of the O(log(m*n)) this version achieves.
What if you need to return the (row, column) position of the match instead of just true or false?
Keep the same binary search, and instead of returning true when value == target, return the pair (mid / cols, mid % cols) directly — those are already the row and column of the match, so no extra work is needed beyond changing what the successful branch returns.
Frequently asked questions
Not quite — the row-by-row approach runs a full O(log n) binary search inside every one of the m rows, which is O(m log n), not O(log m) + O(log n). Those are very different once m and n both get large. The optimal approach gets the true O(log(m*n)) bound by treating the whole grid as one sequence and searching it exactly once.
Reading the matrix row by row in order — row 0 left to right, then row 1 left to right, and so on — is exactly what a 1D array of length rows * cols would look like if you flattened it. Integer division by the column count tells you which row a flattened index falls in, and the remainder tells you how far into that row it is, so you get the same values without ever copying the matrix.
Sorted, chunked data shows up constantly in infrastructure: log shards that are each sorted by timestamp and laid out one after another, or paginated API results where each page is sorted and pages are returned in order. Recognizing that the combined data is really one sorted sequence, instead of treating each chunk separately, is the same insight this problem is testing.
The approaches above still correctly report whether target exists at all, since they only need to find one matching cell. If you needed the number of times target appears, or every position it appears at, you would need to keep searching outward from a found match instead of stopping at the first hit — a small but real change to the loop.