01 Matrix

Problem statement
You are given a grid mat of 0s and 1s. For every cell, find how many steps it takes to reach the nearest 0, moving only up, down, left or right. A 0 cell has distance 0. Return a grid of the same size holding these distances.
The grid always contains at least one 0.
Think of the 0s as healthy data centres and the 1s as sites that need failover: for each site, how many hops is the closest healthy one?
Examples
Example 1
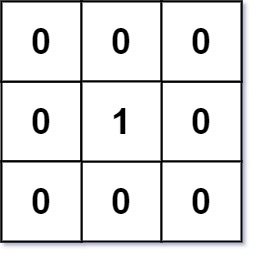
Input: mat = [[0,0,0],[0,1,0],[0,0,0]]
Output: [[0,0,0],[0,1,0],[0,0,0]]
Explanation: The only 1 sits in the centre, and all four of its neighbours are 0, so its distance is 1. Every other cell is already 0.
Example 2
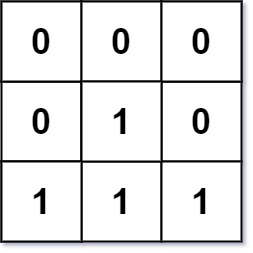
Input: mat = [[0,0,0],[0,1,0],[1,1,1]]
Output: [[0,0,0],[0,1,0],[1,2,1]]
Explanation: The bottom-middle cell's neighbours are all 1s, so the nearest 0 is two steps away (up twice). The other 1s touch a 0 directly, so their distance is 1.
Hints
Approach
Optimal: Two-pass DP
Intuition
Any shortest path from a cell to its nearest 0 moves in some mix of up/down and left/right steps. Split the problem in two. The first pass, going top-left to bottom-right, answers "the nearest 0 reachable by coming from above or from the left": each cell is 1 more than the better of its top and left neighbours, which are already final for this pass. The second pass, going bottom-right to top-left, adds "from below or from the right" in the same way, keeping whichever is smaller.
Why do two passes cover every direction? After pass 1, every cell knows the best route that starts upward or leftward. Pass 2 lets a cell use its bottom and right neighbours, whose values already include everything pass 1 found. Together they combine into the true nearest 0. This is dynamic programming (DP): building each answer from answers already computed for neighbours.
Steps
- Create
dist. Set 0 for every 0 cell and a large value (rows + cols, bigger than any real distance) for every 1. - Pass 1, rows top to bottom, columns left to right: for each 1 cell,
dist = min(dist, top + 1, left + 1)using the neighbours that exist. - Pass 2, rows bottom to top, columns right to left: for each 1 cell,
dist = min(dist, bottom + 1, right + 1). - Return
dist.
Dry run
Example 2, large value = 6:
| cell | after pass 1 (from top/left) | after pass 2 (from bottom/right) |
|---|---|---|
| (1,1) | min(6, 0+1, 0+1) = 1 | stays 1 |
| (2,0) | min(6, 0+1) = 1 | stays 1 |
| (2,1) | min(6, 1+1, 1+1) = 2 | stays 2 |
| (2,2) | min(6, 0+1, 2+1) = 1 | stays 1 |
Here pass 1 already finds every answer; pass 2 matters when the nearest 0 lies below or to the right, such as [[1],[0]], where pass 1 leaves 2 at the top and pass 2 fixes it to 1.
Complexity
Time O(m·n) - The first pass visits every cell once, top-left to bottom-right, and looks at two neighbours. The second pass does the same in the opposite direction. Two passes with constant work per cell are O(m·n). It does the same amount of work as BFS, with no queue.
Space O(1) - extra — The distance grid is the output, so it isn't counted. Nothing else is stored: no queue and no visited marks. That makes this the most memory-friendly option.
from typing import List


class Solution:
    def updateMatrix(self, mat: List[List[int]]) -> List[List[int]]:
        rows, cols = len(mat), len(mat[0])
        big = rows + cols
        dist = [[0 if mat[r][c] == 0 else big for c in range(cols)] for r in range(rows)]

        for r in range(rows):
            for c in range(cols):
                if dist[r][c] == 0:
                    continue
                if r > 0:
                    dist[r][c] = min(dist[r][c], dist[r - 1][c] + 1)
                if c > 0:
                    dist[r][c] = min(dist[r][c], dist[r][c - 1] + 1)

        for r in range(rows - 1, -1, -1):
            for c in range(cols - 1, -1, -1):
                if r < rows - 1:
                    dist[r][c] = min(dist[r][c], dist[r + 1][c] + 1)
                if c < cols - 1:
                    dist[r][c] = min(dist[r][c], dist[r][c + 1] + 1)
        return dist


if __name__ == "__main__":
    print(str(Solution().updateMatrix([[0, 0, 0], [0, 1, 0], [0, 0, 0]])).replace(" ", ""))
print(str(Solution().updateMatrix([[0, 0, 0], [0, 1, 0], [1, 1, 1]])).replace(" ", ""))RecapThe whole problem in a few lines, for the night before
- Spot it: "distance from every cell to the nearest X" on a grid
- Idea: multi-source BFS — put every X in the queue at distance 0 and spread outward; the first visit to a cell is its answer
- Cost: O(m·n) time, O(m·n) space
- Trap: running a separate BFS from each cell is O((m·n)²); start from the targets instead
- Remember: a two-pass DP (top-left, then bottom-right) also works in O(m·n) with no queue, when no cells are blocked
Interview follow-ups
Some cells are walls that can't be crossed. What changes?
In the BFS, skip neighbours that are walls. Everything else stays the same, and the cost is still O(m·n). Walls that no 0 can reach keep
-1, which you can report as "unreachable". The two-pass DP no longer works, because the shortest path may have to wind around walls.Return, for each cell, *which* 0 is the nearest one.
Store the source along with the distance: when a cell is first reached, copy the source label from the cell it came from. Each cell still enters the queue once, so time stays O(m·n). This builds a map of "which data centre serves which site", useful for failover planning.
The grid is 100,000 × 100,000 and doesn't fit in memory.
Process it in horizontal strips that do fit, using the two-pass DP: pass 1 runs top to bottom, strip by strip, keeping only the last row of the previous strip. Pass 2 runs bottom to top the same way. The time is still O(m·n), and memory drops to about one strip plus a boundary row.
Frequently asked questions
It is an ordinary BFS that starts with several cells in the queue instead of one. Because all the starting cells are at distance 0, the search grows outward from all of them together, one ring per step. Each cell is reached first by its nearest source. It's the standard tool for "distance to the nearest X" questions.
Then you'd need a separate search per 1, because each 1 wants its own nearest 0 — that's the brute force. Starting from the 0s answers every cell in one search. The rule of thumb: when many cells ask "how far is the nearest target?", start from the targets.
Any cell can reach any other cell in at most (rows - 1) + (cols - 1) steps, so no real distance is ever that big. Using rows + cols keeps the value safely above every real answer. It also avoids overflow in Java and C++: Integer.MAX_VALUE + 1 wraps around to a negative number.
Both are O(m·n). BFS is the more general idea and carries over to problems like Rotting Oranges or walls and gates, where cells can be blocked. The DP uses no queue and no extra memory, but only works when every cell can be walked through. In an interview, BFS is the expected answer; mentioning the DP is a plus.
"Distance to the nearest healthy resource" is a real question: nearest available replica, nearest region with capacity, how many hops until a failure reaches each node. Multi-source BFS is also how you model something spreading from several places at once, like an outage or a config change rolling out through a network.