Rotting Oranges

Problem statement
You're given an m x n grid where every cell holds one of three values: 0 for an empty cell, 1 for a fresh orange, or 2 for a rotten orange.
Every minute, any fresh orange that sits directly above, below, left, or right of a rotten orange becomes rotten too. Return the smallest number of minutes that must pass until no fresh orange is left anywhere in the grid. If some fresh orange can never be reached, return -1.
This models exactly how a failure or an outage spreads through a fleet: a bad node can bring down its directly connected neighbors one round at a time, and the question is how long the spread takes to finish — or whether some part of the fleet is isolated enough that the failure never reaches it at all.
Examples
Example 1
Input: grid = [[2,1,1],[1,1,0],[0,1,1]]
Output: 4
Explanation: starting from the single rotten orange in the top-left corner, the rot spreads outward one ring of neighbors at a time; the orange farthest away (bottom-right) is the last to turn, at minute 4.
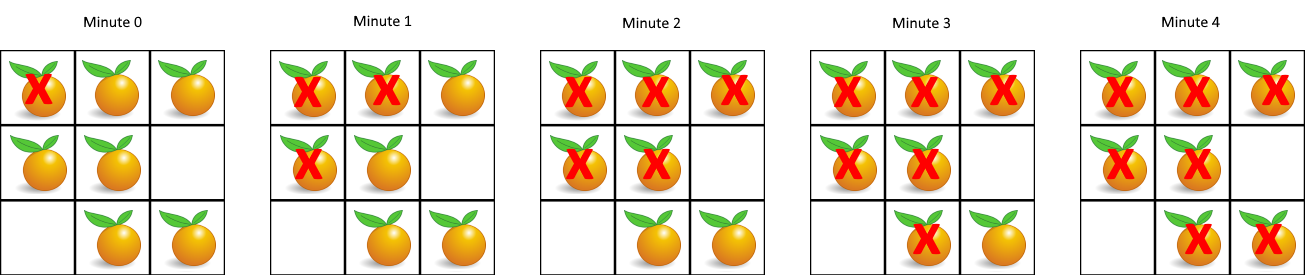
Example 2
Input: grid = [[2,1,1],[0,1,1],[1,0,1]]
Output: -1
Explanation: the fresh orange in the bottom-left corner is surrounded by an empty cell above it and an empty cell to its right, so it's never 4-directionally adjacent to any rotten orange — it can never rot.
Example 3
Input: grid = [[0,2]]
Output: 0
Explanation: there are no fresh oranges anywhere in the grid to begin with, so zero minutes need to pass.
Hints
Approach
Optimal: Multi-source BFS
Intuition
Instead of re-scanning the whole grid every minute, start a breadth-first
search from every initially rotten orange at the same time — that's
what "multi-source" means here. Push all of them into a queue first, tagged
with minute 0. Then process the queue exactly the way any BFS works: pop
a cell, look at its neighbors, and push any fresh one after marking it
rotten and tagging it with one minute later than the cell that turned it.
Because BFS explores in order of distance, the minute tag naturally comes
out correct without ever needing to re-check cells that already turned.
Steps
- Scan the grid once: push every rotten orange's position onto a queue
tagged with minute
0, and count every fresh orange into afreshcounter. - While the queue isn't empty, pop a cell and its minute tag.
- For each of its four neighbors that's still a fresh orange: mark it
rotten, decrease
freshby one, and push it onto the queue tagged with one minute later. - Keep a running maximum of every minute tag seen — that becomes the final answer.
- Once the queue is empty, return that maximum if
freshis0; otherwise return-1, since some fresh orange was never reached.
Dry run
grid = [[2,1,1],[1,1,0],[0,1,1]] (Example 1, 0-indexed rows/cols)
Initial queue: [(0,0,0)] (the one rotten orange, minute 0). fresh = 6.
| pop | minute | fresh neighbors rotted | queue gains |
|---|---|---|---|
| (0,0) | 0 | (0,1) and (1,0) | (0,1,1), (1,0,1) |
| (0,1) | 1 | (1,1) | (1,1,2) |
| (1,0) | 1 | (1,1) already claimed this minute — no new cell | — |
| (1,1) | 2 | (2,1) | (2,1,3) |
| (2,1) | 3 | (2,2) | (2,2,4) |
| (2,2) | 4 | (none left) | — |
The highest minute tag seen is 4, and by that point fresh has dropped
to 0, so the answer is 4 — matching the example. Note how the answer
comes directly from the tag on the last cell popped, not from counting
loop iterations.
Edge cases: a grid with zero rotten oranges and at least one fresh orange
never even starts the queue, so it immediately falls through to the
leftover-fresh check and returns -1; a grid with fresh oranges walled off
by empty cells the same way as Example 2 simply never gets those cells
pushed onto the queue at all.
Complexity
Time O(m·n) - Every cell is added to the queue at most once and popped exactly once, and each pop only checks its 4 fixed neighbors, so the total work is proportional to the number of cells in the grid.
Space O(m·n) - the queue, which in the worst case (a grid that starts almost entirely rotten) holds close to every cell at once.
from collections import deque


class Solution:
    def orangesRotting(self, grid: list[list[int]]) -> int:
        rows, cols = len(grid), len(grid[0])
        queue = deque()
        fresh = 0

        for r in range(rows):
            for c in range(cols):
                if grid[r][c] == 2:
                    queue.append((r, c, 0))
                elif grid[r][c] == 1:
                    fresh += 1

        minutes = 0
        while queue:
            r, c, minute = queue.popleft()
            minutes = max(minutes, minute)
            for dr, dc in [(-1, 0), (1, 0), (0, -1), (0, 1)]:
                nr, nc = r + dr, c + dc
                if 0 <= nr < rows and 0 <= nc < cols and grid[nr][nc] == 1:
                    grid[nr][nc] = 2
                    fresh -= 1
                    queue.append((nr, nc, minute + 1))

        return minutes if fresh == 0 else -1


if __name__ == "__main__":
    print(Solution().orangesRotting([[2, 1, 1], [1, 1, 0], [0, 1, 1]]))  # 4
    print(Solution().orangesRotting([[2, 1, 1], [0, 1, 1], [1, 0, 1]]))  # -1
print(Solution().orangesRotting([[0, 2]])) # 0RecapThe whole problem in a few lines, for the night before
- Spot it: "spreads outward one step per minute from several starting points" on a grid
- Idea: multi-source BFS — push every starting rotten orange first, then expand level by level, tracking the minute each cell turns
- Cost: O(m·n) time and space; naive minute-by-minute full rescans: O((m·n)²)
- Trap: letting a cell that just turned rotten spread again in the same pass — collect this minute's changes separately and apply them together, or the timing comes out too fast
Interview follow-ups
What if oranges could also rot diagonally, not just up/down/left/right?
Only the neighbor-generating step changes — add the four diagonal offsets to the four direction vectors already being checked, so each cell checks 8 neighbors instead of 4. The BFS structure, the queue, the minute tagging, and the final leftover-fresh check are all unaffected; the algorithm still runs in O(m·n) time.
The grid is enormous and doesn't fit in memory on one machine. How would you approach it at scale?
Split the grid into tiles, run BFS independently within each tile, and exchange only the rot state of each tile's border cells with its neighboring tiles after every round — this is the same idea as distributed graph-processing frameworks that process a graph in supersteps (each round, every node's border state syncs before the next round begins). The core per-cell logic doesn't change; what changes is that the "grid" is now partitioned across machines instead of held in one array.
What if you needed to report, for each fresh orange, exactly *which* rotten orange caused it to rot (its "source"), not just the total time?
Store, alongside each minute tag, the coordinates of the cell that caused the rot — when a fresh cell is turned rotten, record the popped cell's position as its source before pushing it. This adds only O(1) extra work per cell, so the algorithm is still O(m·n) overall; it's the same idea as recording a parent pointer during BFS to reconstruct a shortest path afterward.
Frequently asked questions
This is exactly the shape of failure propagation across a fleet: a bad host can take down its directly connected neighbors one round at a time, and modeling "how long until the outage stops spreading, and did anything stay unaffected" is a real capacity-planning and blast-radius question. The same multi-source BFS pattern also shows up in cache invalidation waves and in flood-fill-style health checks across a cluster.
Because they're all spreading during the exact same first minute in real time — starting from only one and running a separate BFS per rotten orange would either need merging multiple time counts together afterward, or would get the timing wrong if run one after another. Pushing every source into the queue before the loop even starts is what makes a single BFS pass correctly account for all of them simultaneously.
Because BFS doesn't process the grid in tidy one-minute batches by default — cells from different minutes can sit in the queue at the same time once multiple rotten oranges are spreading independently. Tagging each cell with its own minute when it's pushed, and tracking the largest tag seen, gives the correct answer regardless of how the queue happens to interleave cells from different minutes.
Not correctly and efficiently as a single pass: DFS explores as deep as possible down one path before backtracking, so the first time it reaches a far-away cell doesn't reliably reflect the fewest number of minutes needed to get there. A DFS-based solution can be made to work (GfG's DFS approach does, by revisiting a cell whenever a shorter time is found), but it does extra repeated work that BFS avoids by construction, since BFS visits cells in increasing order of distance the first time, every time.