Network Delay Time
Problem statement
A network has n nodes, numbered 1 to n. Each entry [u, v, w] in times is a one-way link: a signal sent from node u reaches node v after w time units. A signal starts at node k and travels along every link at once.
Return how long it takes until every node has received the signal. If some node can never receive it, return -1.
This is literally the infra question it sounds like: if a config change, a gossip message or an alert starts at one node, when has the whole cluster heard about it — and is any node cut off?
Examples
Example 1
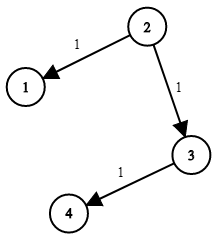
Input: times = [[2,1,1],[2,3,1],[3,4,1]], n = 4, k = 2
Output: 2
Explanation: From node 2, nodes 1 and 3 get the signal after 1 unit. Node 4 is reached through node 3, after 1 + 1 = 2 units. The last node hears it at time 2.
Example 2
Input: times = [[1,2,1]], n = 2, k = 1
Output: 1
Explanation: The only link carries the signal from node 1 to node 2 in 1 unit, so both nodes have it at time 1.
Example 3
Input: times = [[1,2,1]], n = 2, k = 2
Output: -1
Explanation: The signal starts at node 2, but the only link points from 1 to 2, not back. Node 1 never receives it.
Hints
k reaches it. So you need the shortest travel time from k to every node; the answer is the largest of those.Approach
Optimal: Dijkstra with a min-heap
Intuition
The linear-scan version spends O(n) per round just finding the closest unsettled node. A min-heap (priority queue) — a structure that always hands back its smallest item in O(log size) — does that job much faster. Push (time, node) pairs onto it, and pop the smallest each time.
We don't remove old entries when a node's time improves; we just push the new, smaller time. The old entry stays in the heap and pops later with a larger time than the node's current best. When that happens, skip it — this is called lazy deletion, and it's simpler than updating entries in place. The first time a node is popped with its current best time, that time is final.
Steps
- Build
graph[u]: the list of(v, w)links leavingu. - Set
best[k] = 0, others to infinity. Push(0, k)onto a min-heap. - While the heap isn't empty:
- Pop
(t, u). Ift > best[u], it's stale — skip it. - For each link
(v, w)fromu: ift + w < best[v], setbest[v] = t + wand push(best[v], v).
- Pop
- If any node is still at infinity, return
-1; otherwise return the largestbest.
Dry run
Example 1, k = 2:
| pop | stale? | updates / pushes | heap after |
|---|---|---|---|
| (0, 2) | no | node 1 → 1, node 3 → 1 | (1,1), (1,3) |
| (1, 1) | no | none | (1,3) |
| (1, 3) | no | node 4 → 2 | (2,4) |
| (2, 4) | no | none | empty |
Largest time is 2. Edge cases: a link with time 0 is fine, because Dijkstra only needs times that are not negative. In Example 3 the heap empties with node 1 still at infinity → -1.
Complexity
Time O(E log E) - Each successful relaxation pushes one entry onto the heap, so there are at most E pushes, and each push or pop costs O(log E). Stale entries (a node popped again after it was already settled) are skipped in O(1). On sparse networks this is much faster than scanning all nodes every round. For 6,000 links it is roughly 6,000 × 13 ≈ 80,000 heap steps.
Space O(n + E) - The adjacency list holds E links, the heap holds up to E entries, and `best` holds n times. The input is not counted.
import heapq
from typing import List


class Solution:
    def networkDelayTime(self, times: List[List[int]], n: int, k: int) -> int:
        graph: List[List[tuple]] = [[] for _ in range(n + 1)]
        for u, v, w in times:
            graph[u].append((v, w))

        INF = float("inf")
        best = [INF] * (n + 1)
        best[k] = 0
        heap = [(0, k)]
        while heap:
            t, u = heapq.heappop(heap)
            if t > best[u]:
                continue
            for v, w in graph[u]:
                if t + w < best[v]:
                    best[v] = t + w
                    heapq.heappush(heap, (best[v], v))

        answer = max(best[1:])
        return -1 if answer == INF else answer


if __name__ == "__main__":
    print(Solution().networkDelayTime([[2, 1, 1], [2, 3, 1], [3, 4, 1]], 4, 2))  # 2
    print(Solution().networkDelayTime([[1, 2, 1]], 2, 1))  # 1
print(Solution().networkDelayTime([[1, 2, 1]], 2, 2)) # -1RecapThe whole problem in a few lines, for the night before
- Spot it: weighted, non-negative links; "how long until every node is reached?" or "shortest time from one source"
- Idea: Dijkstra — pop the closest unsettled node from a min-heap, relax its links; answer is the largest final time
- Cost: O(E log E) time, O(n + E) space
- Trap: using BFS (ignores link costs), or forgetting to skip stale heap entries and to return
-1for unreachable nodes - Remember: nodes are numbered from 1, so size arrays
n + 1
Interview follow-ups
Return which node receives the signal last, and the path it took.
While relaxing, store
parent[v] = uwheneverbest[v]improves. After Dijkstra, the last node is the one with the largestbest; followparentback tokand reverse the list to get its path. Time and space stay the same. That path is the slowest leg of the rollout — the first place to look when propagation is slow.A link fails. How do you recompute quickly?
For a network this small, simply rerun Dijkstra without that link: O(E log E). If only the nodes whose shortest path used the failed link are affected, you can reset just those (the subtree under the link in the parent tree) and rerun from their neighbours. Production routing protocols do a version of this incremental recompute to converge faster.
Signals can start at several nodes at once. What changes?
Push every start node onto the heap with time 0 before the loop — a multi-source Dijkstra. Each node then gets the time from its nearest source. Everything else stays the same, and so does the O(E log E) cost. This models a change pushed to several regions at the same time.
Frequently asked questions
Every node hears the signal at its own earliest arrival time, which is its shortest path time from k. The whole network is done only when the last node hears it. So you compute the shortest time to every node and take the maximum — the node that is "farthest" in time decides the answer.
BFS finds the fewest links, which is the fastest route only when every link costs the same. Here a path with more links can be faster: k → a → b costing 1 + 1 beats a direct k → b costing 5. Dijkstra accounts for the costs; BFS doesn't.
It relies on "the closest unsettled node is final". A negative link could lead back to a settled node with a smaller time later, breaking that promise. This problem guarantees times from 0 to 100, so Dijkstra is safe. With negative links you'd fall back to Bellman-Ford, which also detects negative cycles.
The heap version is O(E log E) and wins on sparse networks (few links per node), which is the usual case. The linear scan is O(n²) and can win on very dense networks where E is close to n², since it has no heap overhead. Here n is only 100, so both are instant; the heap version is what interviewers expect.
It models how fast something spreads through a network: a config push, a gossip-protocol message, a cache invalidation or a routing update. "How long until everyone has it?" and "is any node unreachable?" are real questions during rollouts and incidents. Link-state routing protocols such as OSPF run Dijkstra to build their routing tables.