Redundant Connection
Problem statement
A tree with n nodes has exactly n - 1 edges connecting everything together with no cycles. You're given n edges instead of n - 1 — one extra edge was added to an otherwise valid tree, creating exactly one cycle somewhere in the graph.
Find one edge that can be removed so that what's left is a valid tree again (still connecting all n nodes, with no cycles). If more than one edge could be removed to fix it, return whichever one appears last in the input list edges.
Examples
Example 1
Input: edges = [[1,2],[1,3],[2,3]]
Output: [2,3]
Explanation: The first two edges already connect nodes 1, 2 and 3 into one tree, so the third edge, [2,3], closes a cycle and is the one to remove.
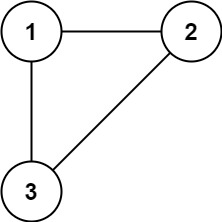
Example 2
Input: edges = [[1,2],[2,3],[3,4],[1,4],[1,5]]
Output: [1,4]
Explanation: The first three edges connect 1 through 2 and 3 to 4, so the fourth edge, [1,4], closes a cycle among nodes 1-4 and is the one to remove; the fifth edge, [1,5], never causes a problem since node 5 wasn't connected to anything yet.
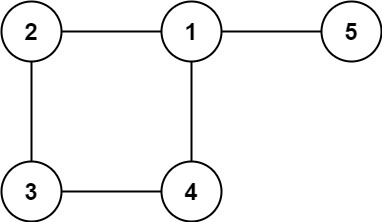
Hints
Approach
Optimal: Union-Find with path compression
Intuition
The brute force approach re-explores the graph with a fresh search for every single edge, which is wasteful once you notice the real question being asked over and over: "are these two nodes in the same connected group?" A Union-Find (Disjoint Set Union) structure answers exactly that question quickly, by keeping track of which connected group each node belongs to and merging groups together as edges are added.
For each edge (u, v), ask Union-Find whether u and v are already in the same group. If they are, this edge connects two nodes that were already connected some other way — it's the redundant edge. Otherwise, merge their groups together and move on. Two standard optimizations — path compression (flattening the structure every time a group is looked up) and union by rank (always attaching the smaller group under the larger one) — are what keep each of these operations fast, even after many merges.
Steps
- Create a Union-Find structure with one group per node, each node initially its own group.
- For each edge
(u, v), in order: find the group each node belongs to. - If
uandvare already in the same group, adding this edge would create a cycle — return[u, v]. - Otherwise, merge the two groups together (attaching the smaller-ranked group under the larger one) and continue.
Dry run
edges = [[1,2],[1,3],[2,3]]
| edge | group of u | group of v | same group? | action |
|---|---|---|---|---|
| (1,2) | {1} | {2} | no | merge → {1,2} |
| (1,3) | {1,2} | {3} | no | merge → {1,2,3} |
| (2,3) | {1,2,3} | {1,2,3} | yes | return [2, 3] |
The moment edge (2,3) is checked, both of its endpoints are already in the same merged group, so it's immediately flagged as the redundant edge — no graph search needed, just two quick group lookups.
Edge cases: the same triangle case as the brute force approach still works identically here — the third edge always finds both endpoints already merged into one group by that point.
Complexity
Time O(n · α(n)) - where α is the inverse Ackermann function, which grows so slowly that it's effectively a small constant for any n that could realistically appear. Each of the n edges triggers a small, near-constant number of find and union operations.
Space O(n) - the parent and rank arrays each hold one entry per node.
class DSU:
    def __init__(self, n: int):
        self.parent = list(range(n + 1))
        self.rank = [0] * (n + 1)

    def find(self, x: int) -> int:
        if self.parent[x] != x:
            self.parent[x] = self.find(self.parent[x])  # path compression
        return self.parent[x]

    def union(self, x: int, y: int) -> bool:
        root_x, root_y = self.find(x), self.find(y)
        if root_x == root_y:
            return False  # already connected: this edge would create a cycle

        if self.rank[root_x] < self.rank[root_y]:
            root_x, root_y = root_y, root_x
        self.parent[root_y] = root_x
        if self.rank[root_x] == self.rank[root_y]:
            self.rank[root_x] += 1
        return True


class Solution:
    def findRedundantConnection(self, edges: list[list[int]]) -> list[int]:
        n = len(edges)
        dsu = DSU(n)

        for u, v in edges:
            if not dsu.union(u, v):
                return [u, v]

        return []


if __name__ == "__main__":
    print(Solution().findRedundantConnection([[1, 2], [1, 3], [2, 3]]))               # [2, 3]
print(Solution().findRedundantConnection([[1, 2], [2, 3], [3, 4], [1, 4], [1, 5]])) # [1, 4]RecapThe whole problem in a few lines, for the night before
- Spot it: a graph with exactly n edges on n nodes (one more than a tree needs) — find the one edge that creates a cycle
- Idea: Union-Find — process edges in order, and the first edge whose two endpoints are already in the same group is the redundant one
- Cost: O(n · α(n)) time (effectively linear), O(n) space (a DFS reachability check per edge is O(n^2))
- Trap: forgetting that the answer must be the edge that occurs *last* in the input among all edges that close the cycle — processing edges in order and returning the first failure automatically satisfies this, but reordering edges before processing breaks it
Interview follow-ups
What if the extra edge could instead create a tree with a directed cycle (LeetCode 685, Redundant Connection II)?
Directed edges add two new failure modes beyond a simple cycle — a node with two parents, and a cycle that doesn't necessarily involve every node — so the Union-Find approach needs an extra pre-check for a node having more than one incoming edge, and careful handling of which of the two problematic edges to remove first. It's a meaningfully trickier variant built on the same Union-Find foundation.
What if you needed to report every redundant edge, in a graph that could have several extra edges instead of just one?
The same Union-Find loop still works with almost no change: instead of returning immediately on the first edge that fails the same-group check, keep a list and append every such edge as it's found, continuing through the rest of the input. Each one found this way is redundant relative to the edges already processed before it.
Frequently asked questions
The problem guarantees there is exactly one edge whose removal would fix the graph, and processing edges strictly in the given order means that edge is also the very first one, in that same order, whose two endpoints turn out to already be connected. Since there's only one such edge to find, "first edge that fails the check" and "the one valid answer, which happens to occur last among the edges forming the cycle" are the same edge.
Without it, repeatedly attaching one group under another in an arbitrary order can build up a long, thin chain of parent pointers, making each future lookup slow. Always attaching the smaller-ranked group underneath the larger one keeps the structure shallow, which is what keeps each find operation fast even after many merges.
Detecting the single extra connection that turns a clean tree-shaped topology — like a spanning tree of network links or service dependencies — into one with a cycle is a very literal real-world version of this problem, and Union-Find is the standard tool for efficiently tracking "are these two nodes already connected?" as a topology is built up incrementally.
No — path compression only changes how quickly future find calls resolve a node's group, it never changes which group a node actually belongs to. The answer returned depends only on which edge's two endpoints are found to already share a group, which is unaffected by how that group lookup happens to be implemented internally.