Linked List Cycle

Problem statement
You are given the head of a singly linked list. Each node's next pointer leads to the next node, and a normal list ends when some node's next is null.
Some lists are wired so that a node further down the chain points its next pointer back to a node that came earlier, instead of ending in null. Follow next from that node and you loop forever without ever reaching the end. This is called a cycle.
Return true if the linked list has a cycle, and false if it ends normally.
Think of a chain of config includes: file A includes file B, which includes file C, which includes file A again. Nothing tells you the chain is done — you just keep resolving includes forever unless you check for exactly this kind of loop first.
Examples
Example 1
Input: head = [3,2,0,-4], pos = 1
Output: true
Explanation: The tail node (-4) points back to the node at index 1 (the node holding 2), so following next cycles through 2 → 0 → -4 → 2 → … forever.
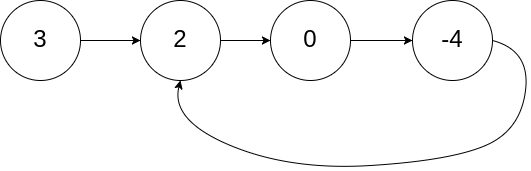
Example 2
Input: head = [1,2], pos = 0
Output: true
Explanation: The tail node (2) points back to the node at index 0 (the node holding 1), so the two nodes point at each other forever.
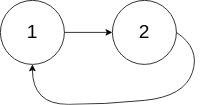
Example 3
Input: head = [1], pos = -1
Output: false
Explanation: pos = -1 means the single node's next is null — the list ends normally, with no cycle.

Hints
Approach
Optimal: Fast & slow pointers
Intuition
Instead of remembering every node, walk the list with two pointers moving at different speeds: slow takes one step at a time, fast takes two. Picture two runners on a track — if the track is a straight line, the faster runner just finishes first. If the track loops back on itself, the faster runner eventually laps the slower one and they end up standing on the same spot.
That's exactly what happens here. If the list has no cycle, fast simply runs off the end (null) before slow does. If the list has a cycle, both pointers eventually enter the loop, and because fast gains one node on slow every step, it cannot skip past slow — it must land on the same node at some point. This beats the hash-set approach because it needs no extra memory at all: just two pointers, regardless of how long the list is.
Steps
- Set both
slowandfasttohead. - While
fastandfast.nextare notnull:- Move
slowone step:slow = slow.next. - Move
fasttwo steps:fast = fast.next.next. - If
slowandfastare now the same node, returntrue.
- Move
- If the loop ends because
fastorfast.nextbecamenull, the list ran out cleanly — returnfalse.
Dry run
List: N0(3) → N1(2) → N2(0) → N3(-4) → N1 (Example 1)
| step | slow | fast | same node? |
|---|---|---|---|
| start | N0(3) | N0(3) | — |
| 1 | N1(2) | N2(0) | no |
| 2 | N2(0) | N1(2) | no |
| 3 | N3(-4) | N3(-4) | yes → return true |
Edge cases: an empty list means fast is already null, so the loop body never runs and we return false. A single node with next equal to null fails the fast.next check on the first pass, so we also return false — we never dereference a null pointer.
Complexity
Time O(n) - Without a cycle, the fast pointer reaches `null` after at most n / 2 iterations, so the pass is O(n). With a cycle, once the slow pointer is inside the loop, the fast pointer closes the gap between them by exactly one node every iteration, so they meet within at most one full lap of the cycle — still bounded by the list's length. The extra speed doesn't cost an extra pass.
Space O(1) - Only two pointers are kept no matter how long the list is; the list itself isn't counted as extra space.
class ListNode:
    def __init__(self, val=0, next=None):
        self.val = val
        self.next = next


class Solution:
    def hasCycle(self, head: "ListNode | None") -> bool:
        slow = head
        fast = head
        while fast and fast.next:
            slow = slow.next
            fast = fast.next.next
            if slow is fast:
                return True
        return False


def _build_list(values, pos):
    if not values:
        return None
    nodes = [ListNode(v) for v in values]
    for i in range(len(nodes) - 1):
        nodes[i].next = nodes[i + 1]
    if pos != -1:
        nodes[-1].next = nodes[pos]
    return nodes[0]


if __name__ == "__main__":
    print(str(Solution().hasCycle(_build_list([3, 2, 0, -4], 1))).lower())  # true
    print(str(Solution().hasCycle(_build_list([1, 2], 0))).lower())  # true
print(str(Solution().hasCycle(_build_list([1], -1))).lower()) # falseRecapThe whole problem in a few lines, for the night before
- Spot it: "does this linked list ever loop back on itself?" — no length is given up front, and following
nextmight never reachnull - Idea: walk with two pointers,
slow(1 step) andfast(2 steps); if a cycle exists they must land on the same node - Cost: O(n) time, O(1) space (the hash-set version: O(n) time, O(n) space)
- Trap: checking only
fast != nullbefore jumping two steps — crashes on anullfast.nextwhen the list has no cycle
Interview follow-ups
Return the actual node where the cycle begins, not just whether one exists.
After
slowandfastmeet inside the loop, reset one pointer back toheadand leave the other at the meeting point. Then move both one step at a time. They are guaranteed to meet again exactly at the first node of the cycle. This works because of the distances involved: the steps fromheadto the cycle's start equal the steps from the meeting point back around to that same start, once you account for how farfasthad already lappedslow. It's still O(n) time and O(1) space — just a second, shorter walk after the first one finds the meeting point.The list is a chain of symlinks resolved by a background worker, and another thread can rewrite a node's
nextpointer while you are mid-scan. How would you detect a cycle safely?The two-pointer trick assumes the structure doesn't change underneath it while it runs, so a concurrent writer breaks that assumption — you could read a
nextpointer that changes between your two accesses. One option is to take a read lock (or snapshot the chain into an immutable copy) before scanning, which costs the O(n) memory the pointer approach was trying to avoid. Another is to tag each node with a version or generation counter, and if it changes mid-walk, abort and retry the scan rather than trust a possibly-stale result.
Frequently asked questions
The pointer-chasing part is the practice, but the pattern it teaches shows up constantly in infra work: a chain of symlinks that loops back on itself, a config file that includes another file that eventually includes the first one again, or a chain of HTTP redirects that never terminates. Detecting "have I been here before, in constant memory" before you follow a chain blindly is exactly this problem.
If we only checked fast != null, then on a list with an odd number of nodes and no cycle, fast.next would be null on the last useful iteration, and calling fast.next.next would try to read .next off a null reference and crash. Checking fast.next first guarantees there really is a next-next node to jump to.
No. Both approaches compare node references (is this the exact same node object?), never node values. Two different nodes that happen to hold the value 5 are still two different objects, so neither the set nor the pointer comparison would treat them as a repeat. That is exactly why linked-list cycle problems, unlike array duplicate problems, never need to look at .val at all.
This problem only asks for true or false. A very close, and slightly harder, problem (LeetCode 142, Linked List Cycle II) asks you to return the actual node where the loop begins, which needs a second phase of the same two-pointer idea — see the first follow-up below.