Remove Nth Node From End of List

Problem statement
You're given the head of a singly linked list. Remove the node that sits n positions from the end of the list (so n = 1 means the very last node, n = 2 means the second-to-last, and so on), then return the head of the list with that node gone.
It's guaranteed that n is never larger than the number of nodes in the list, so there's always a valid node to remove — including the possibility that the node to remove is the head itself, which leaves a shorter list (or an empty one, if there was only one node to begin with).
Examples
Example 1
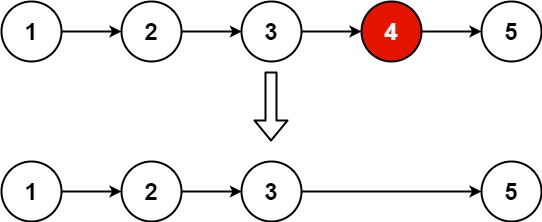
Input: head = [1,2,3,4,5], n = 2
Output: [1,2,3,5]
Explanation: Counting from the end, node 4 is 2nd from the end, so it's the one removed, leaving [1, 2, 3, 5].
Example 2
Input: head = [1], n = 1
Output: []
Explanation: The only node is trivially 1st from the end, so removing it leaves an empty list.
Example 3
Input: head = [1,2], n = 1
Output: [1]
Explanation: Node 2 is 1st from the end (the last node), so it's removed, leaving just [1].
Hints
Approach
Optimal: Fast and slow pointers (one pass
Intuition
The two-pass approach needs to know the list's length before it can find the right position, which means walking the list twice. A pair of pointers that start a fixed distance apart and then move together, one step at a time, removes the need to count anything first: keep that gap at exactly n + 1 nodes, and once the leading pointer falls off the end of the list, the trailing pointer is sitting exactly one node before the one that needs to be removed.
Using a dummy node before the real head, just like in the brute force approach, means the trailing pointer can safely reach and update even the head's own predecessor, without a separate special case.
Steps
- Create a
dummynode whosenextpoints athead. - Set both
fastandslowtodummy. - Move
fastforwardn + 1times, opening up a gap ofn + 1nodes betweenfastandslow. - While
fastis not null, move bothfastandslowforward one step at a time — the gap between them stays exactlyn + 1. - Once
fastbecomes null,slowis sitting exactly one node before the target: unlink it withslow.next = slow.next.next. - Return
dummy.next.
Dry run
head = [1,2,3,4,5], n = 2 (so fast starts n + 1 = 3 nodes ahead of slow)
| stage | fast | slow |
|---|---|---|
| after opening the gap | node 3 | dummy |
| move 1 | node 4 | node 1 |
| move 2 | node 5 | node 2 |
| move 3 | null | node 3 |
fast becomes null after the third move, leaving slow on node 3. slow.next is node 4 — the node 2nd from the end — so slow.next = slow.next.next correctly skips it, leaving [1, 2, 3, 5], in a single pass over the list.
Edge cases: removing the only node (head = [1], n = 1) opens a gap of n + 1 = 2 from dummy, which lands fast past the single real node at null right away, leaving slow at dummy; unlinking dummy.next then correctly empties the list. The gap size, n + 1 rather than n, is exactly what lets slow end up one node before the target instead of on it.
Complexity
Time O(n) - fast visits every node exactly once as it moves ahead and then in lockstep with slow, so the whole list is walked only a single time, answering the problem's own one-pass follow-up.
Space O(1) - only the dummy node and the two pointers, fast and slow, are kept, regardless of the list's length.
# Definition for singly-linked list.
class ListNode:
    def __init__(self, val=0, next=None):
        self.val = val
        self.next = next


class Solution:
    def removeNthFromEnd(self, head: ListNode, n: int) -> ListNode:
        dummy = ListNode(0, head)
        fast = slow = dummy

        # Move fast n + 1 nodes ahead of slow.
        for _ in range(n + 1):
            fast = fast.next

        # Move both until fast falls off the end; slow lands just before the target.
        while fast:
            fast = fast.next
            slow = slow.next

        slow.next = slow.next.next
        return dummy.next


def build_list(values):
    dummy = ListNode(0)
    current = dummy
    for v in values:
        current.next = ListNode(v)
        current = current.next
    return dummy.next


def to_list(node):
    values = []
    while node:
        values.append(node.val)
        node = node.next
    return values


if __name__ == "__main__":
    print(to_list(Solution().removeNthFromEnd(build_list([1, 2, 3, 4, 5]), 2)))  # [1, 2, 3, 5]
    print(to_list(Solution().removeNthFromEnd(build_list([1]), 1)))              # []
print(to_list(Solution().removeNthFromEnd(build_list([1, 2]), 1))) # [1]RecapThe whole problem in a few lines, for the night before
- Spot it: "remove/find the kth node from the end" of a singly linked list — the problem itself often hints at doing it in one pass
- Idea: dummy node before head + two pointers, fast starts n + 1 ahead of slow; when fast falls off the end, slow is right before the target
- Cost: O(n) time, O(1) space either way (the two-pass version needs two full walks, the one-pass version needs only one)
- Trap: opening the gap by n instead of n + 1 leaves slow pointing *at* the target instead of just before it, so the unlink line fails or removes the wrong node
Interview follow-ups
What if the list were doubly linked instead of singly linked?
With a prev pointer available on every node, the node to remove could be found in a single forward pass without needing a dummy node or a second trailing pointer at all — once you're at the target node, prev.next = target.next and target.next.prev = prev (if target.next exists) does the unlinking directly.
What if you needed to remove every kth node from the end, not just the nth?
The same fast/slow pointer gap trick still applies, but instead of stopping after one removal, you'd repeat the process: after removing one node, restart the gap-opening step from the new dummy.next, or track positions from the end in one full pass and remove during a second pass — the one-pass version becomes noticeably trickier to keep correct once multiple removals interact with each other's positions.
Frequently asked questions
If the node to remove turns out to be the head itself, you need something with a next pointer sitting before head to update — but head has no such predecessor of its own. The dummy node stands in as that predecessor for every case, including removing the head, so there's no special-case branch needed anywhere in the code.
The goal is for slow to land on the node just before the one being removed, not on the target node itself, since removing a node means updating the next pointer of whatever comes right before it. Opening the gap to n + 1 instead of n is exactly what shifts slow one node earlier than the target, landing it in the right spot to do the unlinking.
Trimming a fixed number of entries off the tail of a linked structure in a single streaming pass — without knowing the total length ahead of time — matches situations like discarding the oldest few entries of a bounded, append-only log or event buffer where re-reading the whole thing twice would be wasteful.
The problem defines n = 1 as the very last node, so it's 1-indexed by definition, and both approaches are built around that: the two-pass approach computes position length - n (which correctly lands on the last node when n = 1), and the one-pass approach opens a gap of n + 1 for the same reason. Mixing up the indexing convention is a common source of off-by-one bugs in this problem.